


Absolutely. In fact, Python is the industry-standard language for deep learning. While the heavy mathematical lifting is often written in faster languages like C++ or CUDA for performance, Python acts as the "glue" that allows you to build, train, and deploy complex neural networks with readable, high-level code.
As of 2026, the ecosystem is more robust than ever, with a few key frameworks dominating the field.
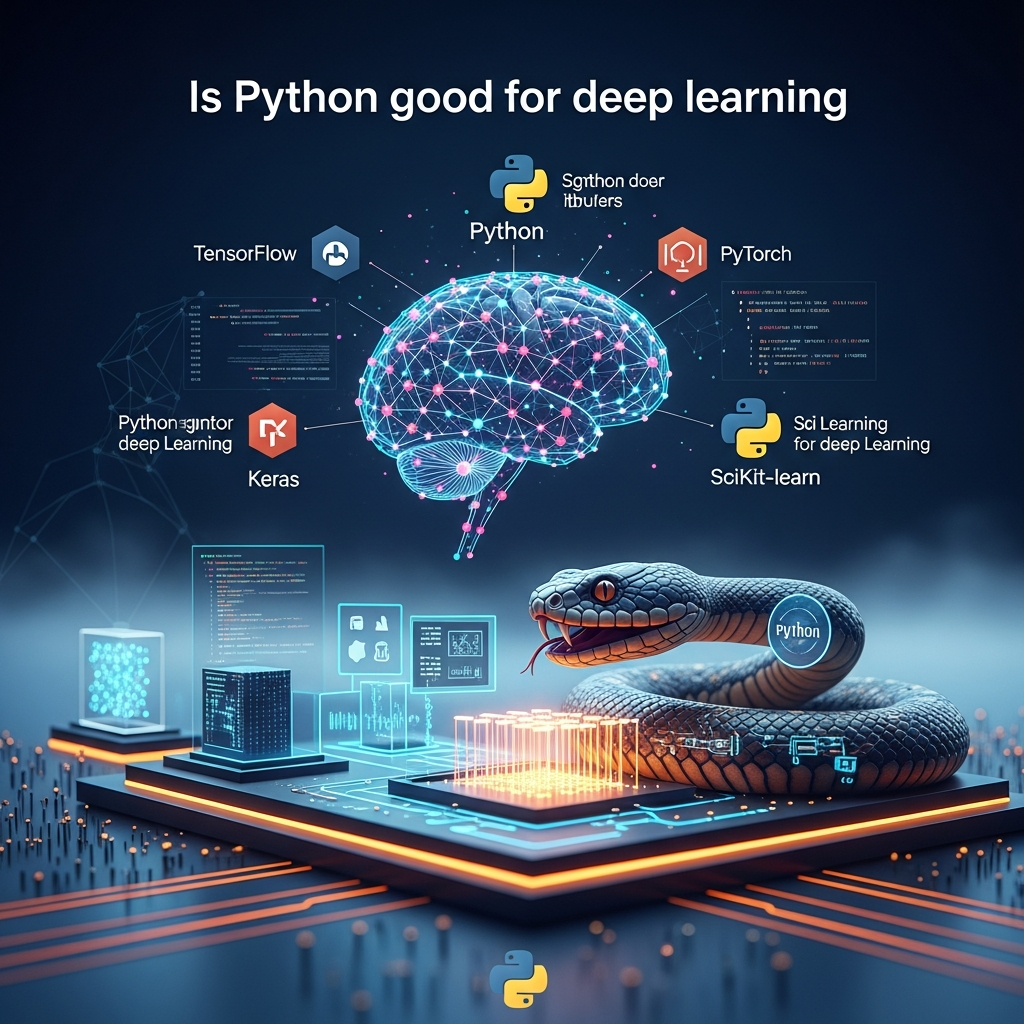
🏆 The "Big Three" Frameworks
Most deep learning projects use one of these three libraries. Choosing between them usually depends on whether you're doing academic research or building production-ready apps.
Framework
Best For
Key Feature
PyTorch
Research & Modern AI
Dynamic Computation Graphs: You can change how the model behaves while it's running, making it very "Pythonic."
TensorFlow
Enterprise & Production
Scalability: Excellent for deploying models across massive server clusters or mobile devices (via TF Lite).
Keras
Beginners & Prototyping
Simplicity: A high-level API (now multi-backend) that lets you build a neural network in just a few lines of code.
🛠️ The Supporting Cast
Deep learning doesn't happen in a vacuum. You’ll almost always use these "helper" libraries alongside the main frameworks:
NumPy: The foundation for all numerical data in Python.
Pandas / Polars: Used for cleaning and preparing your datasets before they hit the model.
Hugging Face Transformers: The go-to for anything involving Large Language Models (LLMs) or Natural Language Processing.
OpenCV: Essential if your deep learning project involves "Computer Vision" (analyzing images or video).
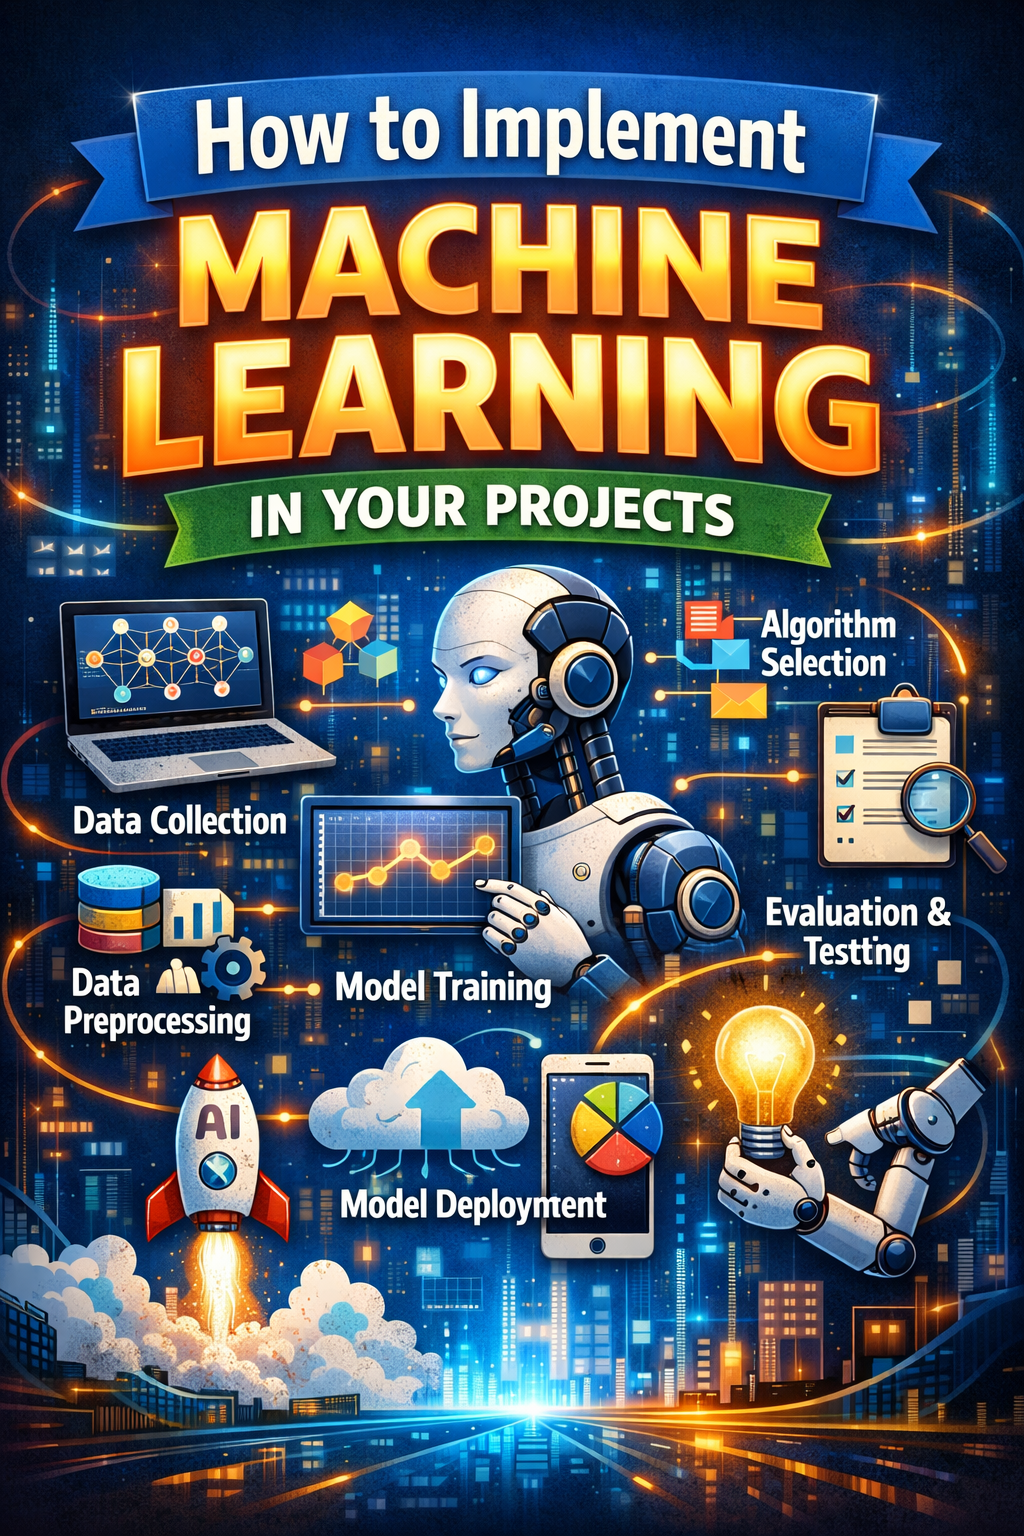
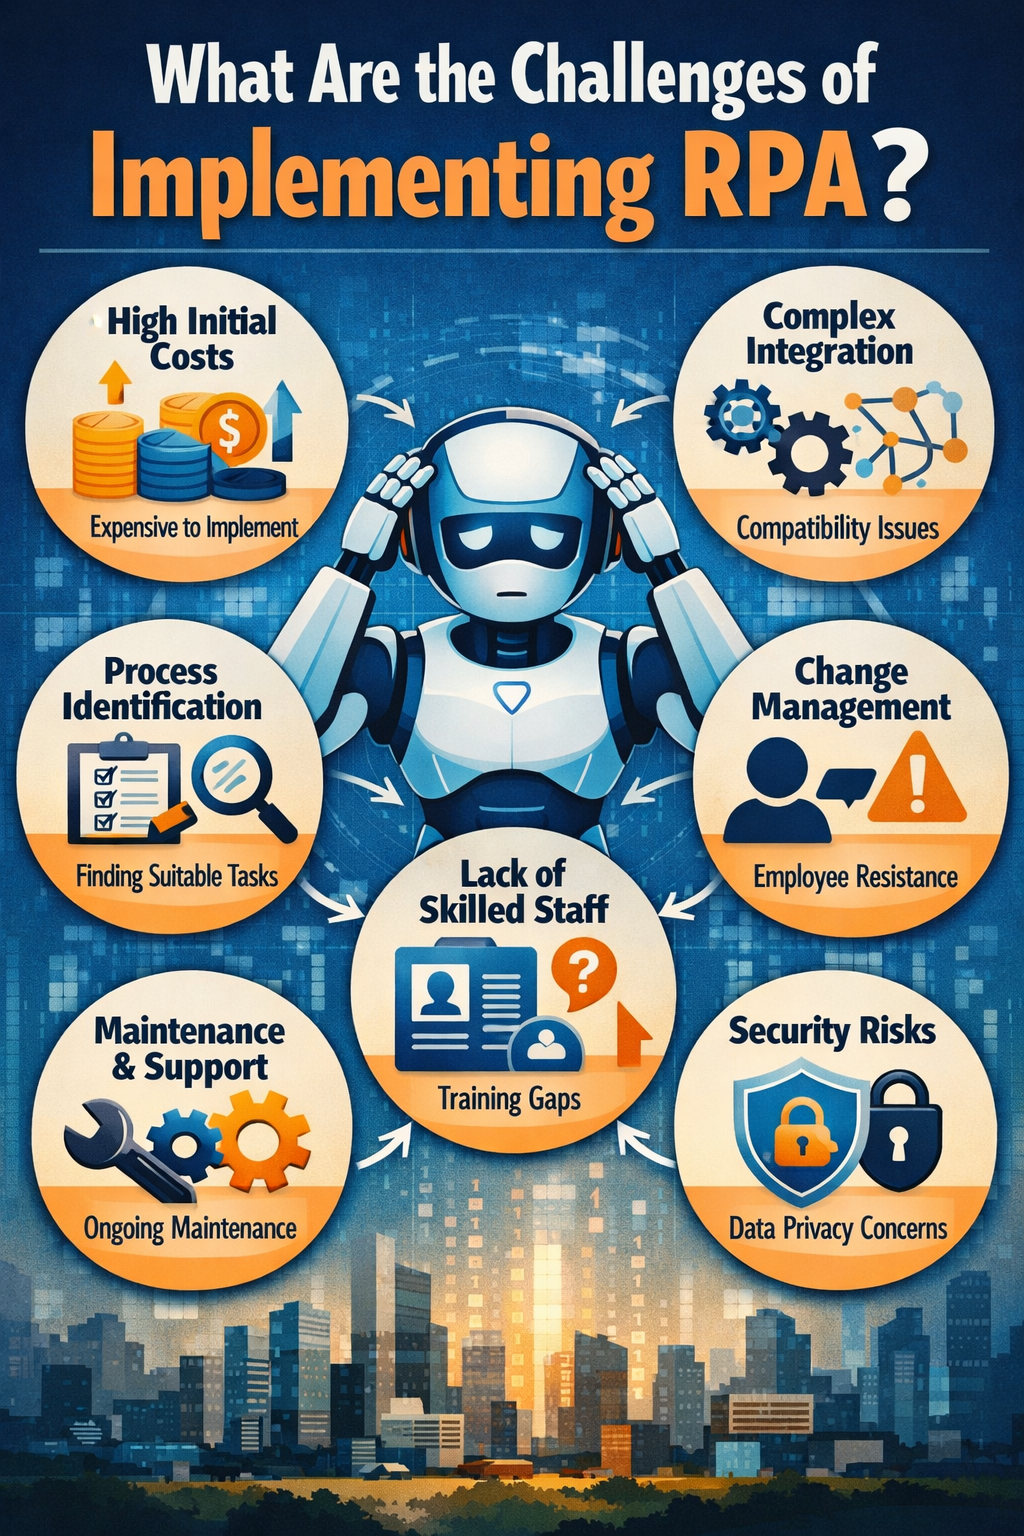
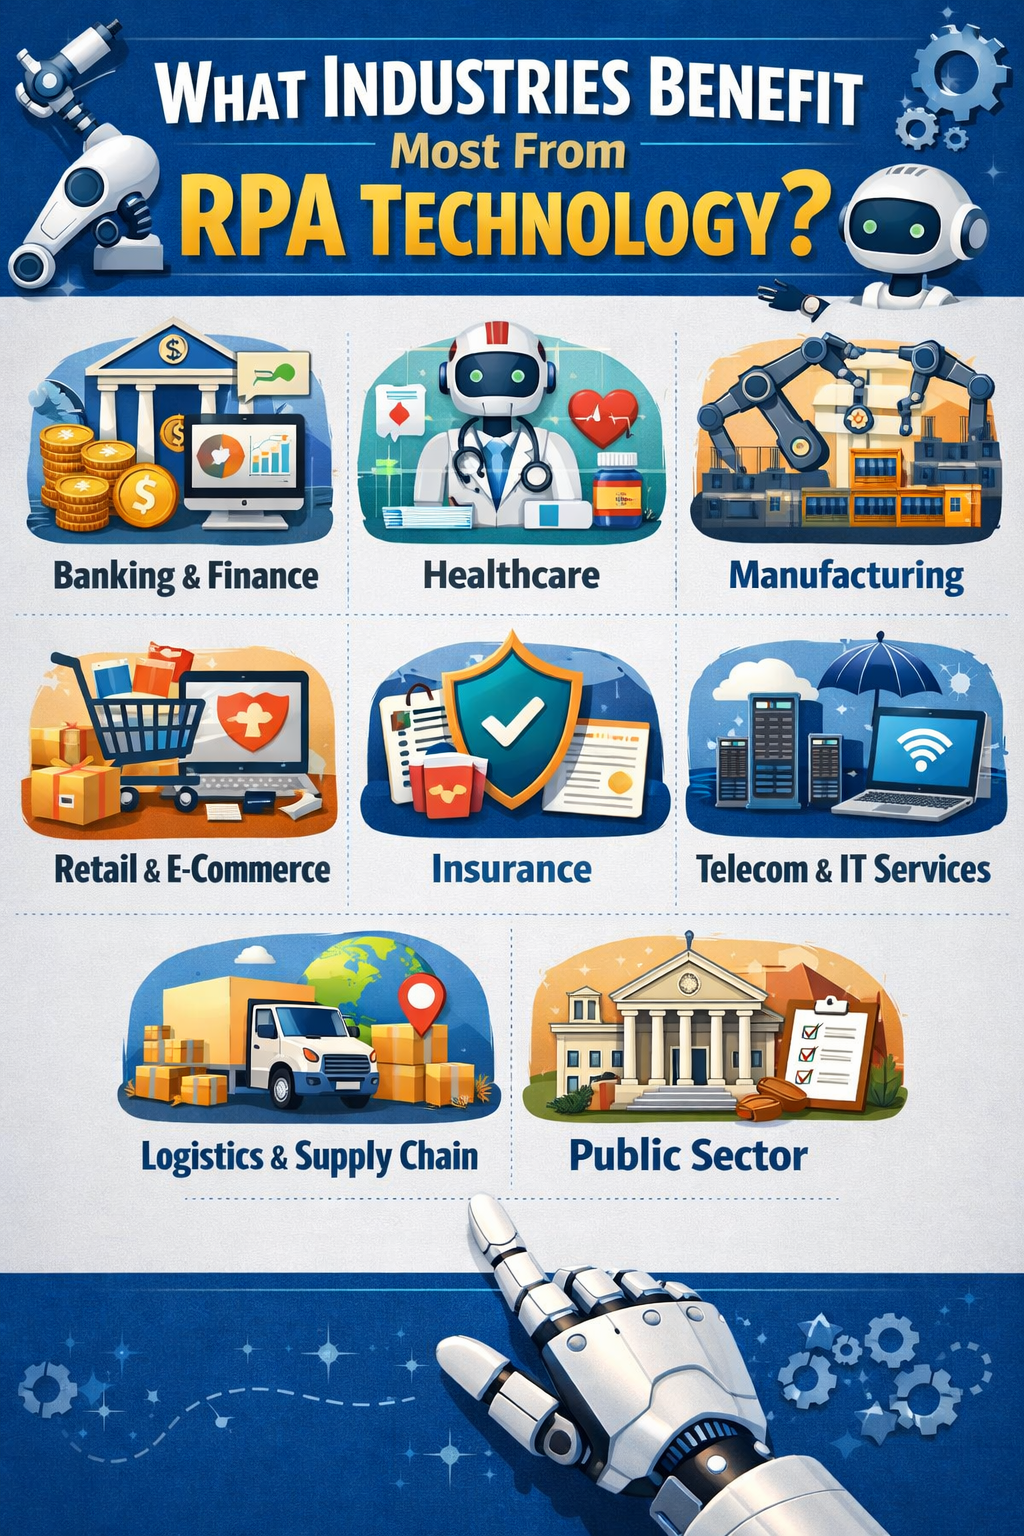
Artificial Intelligence Certification Course Provides Deep Diving into Machine Learning & Deep Learning Training by Highly Experienced ProfessionalsBecome master in AI Certification program, Learn R vs Python, TensorFlowvsKerasvsTFLearn, Deep divine into Machine Learning, Recurrent Neural Networks and LSTMs, convolutional neural networks etc
Dryer vent cleaning dallas tx\n Air Duct cleaning dallas tx\n carpet cleaning dallas tx\n upholstery cleaning dallas tx\n Dryer vent cleaning near me\n is rubbing alcohol flammable after it dries\n"}" data-sheets-userformat="{"2":833,"3":{"1":0},"9":0,"11":3,"12":0}">Do you realize that there are more than 12k dryer vent fires happen every year?
These flames prompted 300 harmed and 15 dead individuals.
The explanation for these flames is the disregard of normal dryer vent cleaning.
Having a build up develop inside your dryer can cause a huge number of issues for your home and your dryer.
It can lead your unit to run increasingly slow can cause unnecessary utilization and vitality bills.
You don't need to manage high utility expenses!Dryer Vent Cleaning Dallas TXAir Duct Cleaning DallasCarpet Cleaning Dallas TXUpholstery Cleaning Dallas TXProfessional Unclog Dryer Duct ServiceYour Safety Is Urgent Precaution!Professional Dryer Vent CleanersShould I clean my dryer?How Long Can A Dryer Vent Be?How High Should A Dryer Vent Be Off The Ground?Do dryers need to be vented outside?Best way to clean dryer ventHow Can I Make My Dryer Work Better?Who can clean my dryer vent?How Do I Get The Smell Out Of My Dryer?Is rubbing alcohol flammable after it dries?How do you deodorize a dryer?How Do I Clean The Inside Of My Dryer?How To Clean Your Dryer Machine Deeply!How do you deep clean a dryer?Why is there no lint in my dryer?How To Clean Your Clothes Dryer ?How do you know if your dryer vent is clogged?5 Warning Signs That it’s Time to Clean Your Dryer VentWhy Should the Dryer Vent be Cleaned?Dryer Vent Cleaners Near MeHow Much Does It Cost To Clean Dryer & Vent?Dryer vent cleaning dallas tx\n Air Duct cleaning dallas tx\n carpet cleaning dallas tx\n upholstery cleaning dallas tx\n Dryer vent cleaning near me\n is rubbing alcohol flammable after it dries\n"}" data-sheets-userformat="{"2":833,"3":{"1":0},"9":0,"11":3,"12":0}">Dryer Vent Cleaning Dallas TXoutdoor lint trapDryer air vent cleaningDryer Vent Cleaning Dallas TXdryer vent cleaning near meDryer lint trapDryer Vent Cleaning Dallas TXclean lint from dryer ventbest way to clean out dryer ventWhat is code for dryer vent?dryer vent cleaning companies near mebest way to clean dryer ventcleaning lint out of dryeroutdoor dryer vent lint traplaundry vent cleaningprofessional dryer vent cleaningbest way to clean dryer ventlowes dryer vent cleanerdryer vent cleaning pricelint cleaner for dryer ventdryer vent cleaning companies near meDryer vent cleaning dallas tx\n Air Duct cleaning dallas tx\n carpet cleaning dallas tx\n upholstery cleaning dallas tx\n Dryer vent cleaning near me\n is rubbing alcohol flammable after it dries\n"}" data-sheets-userformat="{"2":833,"3":{"1":0},"9":0,"11":3,"12":0}">affordable air duct cleaningair duct cleaning costduct cleaning costair duct cleaning near meduct cleaning near meair duct cleaning processduct cleaning servicesdust after duct cleaningfurnace duct cleaninghow often clean ductshow to clean air ductsis cleaning air ducts worth itis duct cleaning a waste of moneyUV light installationAir Duct Mold Removalmold in air conditionerAir Vent Cleaning ServicesVentilation Duct Cleaning